Showing posts with label Developer Tools. Show all posts

Wednesday, December 28, 2022

OCI Queue is now available in all commercial regions

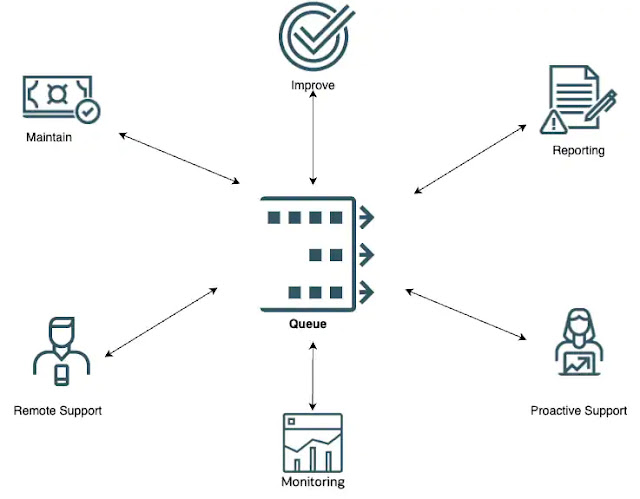
We’re pleased to announce that Oracle Cloud Infrastructure (OCI) Queue service is now generally available in all OCI commercial regions, with the non-commercial regions following shortly. OCI Queue provides a serverless, high-performance messaging solution for asynchronous interprocess communication, allowing services and applications to be decoupled and event-driven. The service is priced on API calls, with the first million calls each month being free.

Oracle Database Certification, Database Exam, Database Career, Database Jobs, Database Prep, Database Skills, Database Prep Exam

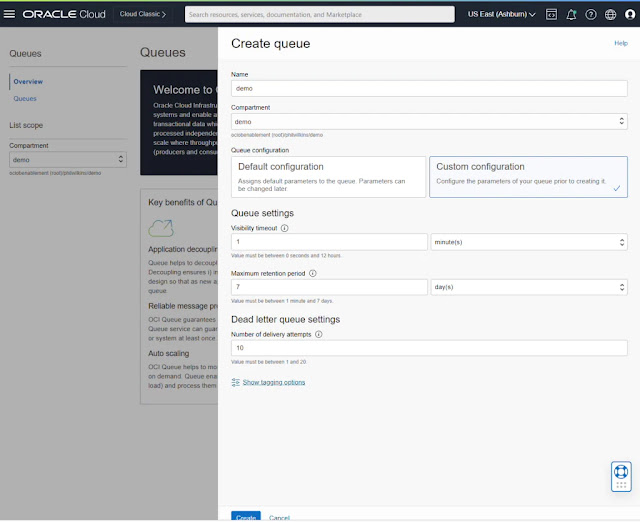
The service includes an intuitive user interface for configuring, creating, and managing queues, along with Terraform support. The service is supported with REST APIs and SDKs for multiple languages, including Java and Python, for not only sending and receiving messages on the queues but also configuring and managing the queues. With REST APIs, the service also supports the use of the STOMP protocol, and other messaging protocols get support in the future.

The Oracle Architecture Center and public GitHub repositories include example and referenceable implementations that you can deploy to see queues being used and see code putting the APIs and SDKs into use.

OCI Queue capabilities


The service provides the following features:

◉ Delivery assurance
◉ Automatic scaling based on demand
◉ Highly available with availability domain and fault zone redundancy
◉ OCI Queue messages are encrypted in flight and at rest.
◉ Implementation agnostic
◉ Provision of dead letter queues to hold messages that have failed delivery
◉ Strong access control managed through policies controlled by OCI Compartments and Identity and  Access Management (IAM) services
◉ Messages in batches to ensure efficiency

Oracle Database Certification, Database Exam, Database Career, Database Jobs, Database Prep, Database Skills, Database Prep Exam

Consumption management


The consumption of messages provides the means to control their visibility. When one consumer takes a message, it isn’t visible to any other consumers but retained on the queue until the first consumer confirms successful receipt or is timed out. With this method, the consumer can change how long a message remains hidden if its transaction takes longer than expected.

Oracle Database Certification, Database Exam, Database Career, Database Jobs, Database Prep, Database Skills, Database Prep Exam

The process uses the following steps:
  1. A producer sends a message to the queue with the default message retention time. The producer receives confirmation that the Queue service received and stored the message.
  2. Consumer A receives the message, which it is supposed to process within Visibility Timeout A.
  3. Consumer B receives nothing because the only available message was already consumed by Consumer A.
  4. Consumer A fails to process the message within Visibility Timeout A, so it updates the message to extend the visibility timeout.
  5. Consumer B tries to receive a message again but can’t because the only available message was consumed and extended by Consumer A.
  6. The extended visibility timeout elapses, and the message becomes visible again.
  7. Consumer B tries to receive a message a third time. Consumer B receives the message, which is supposed to process within Visibility Timeout B.
  8. Consumer A tries to receive the message but receives nothing because Consumer B consumed the message. Consumer A can no longer extend the message’s visibility timeout or delete the message.
  9. Consumer B processes the message successfully and tries to delete the message from the queue. Consumer B receives confirmation that the message was permanently deleted, so it can’t be delivered to any other consumer.
Source: oracle.com

Friday, April 15, 2022

Develop XR With Oracle Ep 3: Computer Vision AI, ML, and Metaverse

This is the third piece in a series on developing XR applications and experiences using Oracle and focuses on XR applications of computer vision AI and ML and its related use in the metaverse.

The first piece can be found here and the second piece can be found here.

Again, I will specifically show applications developed with Oracle database and cloud technologies, HoloLens 2, Mixed Reality Toolkit, and Unity platform.

Throughout the blog, I will reference this corresponding demo video.


Extended Reality (XR), Metaverse, and HoloLens


I will refer the reader to the first piece in the series for an overview of XR and Hololens.

The first blog in this series was based on a data-driven microservices workshop and demonstrated a number of aspects that will be present in the metaverse, such as online shopping, by interacting with 3d models of food/products, 3d/spatial real-world maps, etc. as well as backend DevOps (Kubernetes and OpenTelemetry tracing), etc. 

The second blog was based on a number of graph workshops and demonstrated visualization, creation, and manipulation of models, notebooks, layouts, and highlights for property graph analysis used in social graphs, neural networks, and the financial sector (eg, money laundering detection).

In both of these blogs and in this third blog as well, the subject matter can be shared and actively collaborated up, even in real-time, remotely.  These types of abilities are key to the metaverse concept and will be expanded upon and extended to concepts such as digital doubles in these future pieces. 

This blog will not go into computer vision AI in-depth and will instead focus on the XR-enablement of it and Oracle database and cloud.

Capabilities and Possibilities of Computer Vision with XR


Computer vision AI provides a number of capabilities including image classification, object detection, text detection, and document AI.  

I predominantly use the Hololens to demonstrate concepts in this series as it is the technology closest to what will be the most common and everyday usage of XR in the future, however, the concepts I show in these blogs can be applied to one extent or another in different flavors of XR and devices (and indeed I will be giving examples of such in future blogs).

One thing that most, if not all, of these devices, have in common is a visual interface (ie computer and camera) between the user and the real world. Inherently this has the capability of capturing and processing the visual stimuli surrounding the user and so the link between it and Computer Vision AI is a logical and synergistic one.

This is also true of AI audio and speech which I will also be demonstrating in a future piece.

Image classification and object detection


Imagine the potential to help those with vision impairment, Alzheimer’s, ... by having the XR device give contextual audio and visual feedback about one's surroundings.
 
The first part of the video shows object detection applied to XR. These are the steps involved...

1. A picture of the user's current view is taken by the Hololens (I use an explicit button for this but of course, it could be done automatically, periodically, in reaction to voice command, etc.).

2. This image is automatically uploaded to Oracle object store and database for further analysis. This in and of itself is a handy feature for storing data retrieved from the users' surroundings without the user needing to explicitly instruct it to or even be aware of the various contextual, etc. information being gathered.  

3. The image is then processed by the Vision AI service and a JSON response containing the name, confidence, bondingPolygon normalizedVertices, categorization, etc. is returned to the Hololens.  This is what the image processing and JSON response sent to the Hololens look like in the Oracle cloud console...

Develop XR, Database, Database Exam Prep, Database Career, Database Jobs, Database Material, Oracle Database Guides

4. The Hololens app then processes this JSON, using the vertices/coordinates to recreate the polygons/rectangles and labels. 

5. The location of the user (ie the Hololens headset camera) was saved when the initial picture was taken and a raycast is made from that point, through the coordinates of the 2d rectangles, and onto the  3d spatial surface mesh of the room. (Note the 2d representation is only shown in the demonstration to illustrate the routine described and likely in an actual app, only the end result of the spatially mapped cubes would exist.)

6. 3d cubes are then created at the intersection points of these raycasts on the surface mesh.

7. In addition, once created, the labels are fed to a speech-to-text program that speaks the object's name.  This audio is also 3d spatially mapped.  

8. This provides an extremely efficient and fast technique as a single 2d image is used to map the enter view visually and audibly in 3d and this mapping persists in the exact same locations beyond restarts of the Hololens/app.  (The accuracy and so forth could of course be enhanced further with multiple takes/pics, and captured automatically without the user needing to push a button, etc.)

Develop XR, Database, Database Exam Prep, Database Career, Database Jobs, Database Material, Oracle Database Guides

Imagine the potential to assist with vision impairment, Alzheimer’s, identification of unknown and difficult to isolate items, analysis of threats, interests, etc. by having the XR device give contextual audio and visual feedback about one's surroundings!

This information/representation can in turn be shared in the metaverse across any number of different XR devices (that includes basic phones and simple computer monitors) to facilitate digital doubles, collaboration, etc. in a very efficient and lightweight manner that simultaneously takes advantage of the powerful capabilities of the Oracle database and/in cloud.

Document AI


Imagine using XR and AI to enhance social interactions and engage in more meaningful conversations IN REAL LIFE.

The second part of the video shows the use of the document AI service, again with the Hololens camera capture technique used in the first part of the video, except this time text from the picture (with varying orientation, distance, etc.) is identified. Again this can be used for helping the user read, etc. as in the object detection example, and can also be fed into the Oracle database's powerful ML capabilities to run processing against any number of models, notebooks, etc. In this case, I scan books. This is a shot of that picture with the text processed, in the OCI console.

Develop XR, Database, Database Exam Prep, Database Career, Database Jobs, Database Material, Oracle Database Guides

We could, as I did in the first blog, use this to make suggestions as far as other books that are related or, as I did in the second blog, do some graph analysis to find correlations and commonalities.  In this particular example, however, I have fed the text to a number of  GPT-3 conversation models which then feedback a conversational response. This response, or again any information from various models, can be given to the user to, eg, strike up a conversation with the owner of the books.

Develop XR, Database, Database Exam Prep, Database Career, Database Jobs, Database Material, Oracle Database Guides

This of course is not limited to books or conversations.  The possibilities really are endless as far as the use of this combination of XR and providing the user with information and analysis about the environment they are in (something Oracle tech enables perfectly). 

I can also imagine the user advertising or "wearing" information about themselves the same way they wear clothes, etc. but in a potentially more complex, conveying fashion (meaning "fashion" in both senses of the word and meaning "senses" in both definitions of that word).  The metaverse is full of talk of companies finding new ways to advertise and interactions in a virtual world.  Users should be at least as empowered to express themselves and to do so in the real world.

Source: oracle.com

Wednesday, April 13, 2022

Develop XR with Oracle Cloud, Database on HoloLens, Ep 2: Property Graphs, Data Visualization, and Metaverse

This is the second piece in a series on developing XR applications and experiences using Oracle.

The first piece can be found here

Again I will specifically show applications developed with Oracle database and cloud technologies, Hololens 2 (Microsoft Mixed Reality Headset), MRTK (Mixed Reality Toolkit) APIs (v2.7.2), and Unity (v2021.1.20f) platform.

Read More: Develop XR with Oracle Cloud, Database on HoloLens, Ep 1: Spatial, AI/ML, Kubernetes, and OpenTelemetry

Throughout the blog, I will reference a corresponding demo video found here 

Extended Reality (XR), Metaverse, and HoloLens

I will refer the reader to the first piece in the series for an overview of XR and Hololens.

The first blog in this series was based on a data-driven microservices workshop and described a number of aspects that will be present in the metaverse such as online shopping, DevOps, etc. and I will continue to delve into these areas in this series. One area in particular that I will focus more and more on is collaboration. The graphs in this workshop including models, notebooks, etc. can all be shared and actively collaborated up, even in real-time, remotely. These types of abilities will be expanded upon and extended to concepts such as digital doubles, etc. in these future pieces. 

This blog will not go into property graph concepts deeply and will instead focus on the XR-enablement of them using examples in existing graph workshops.

Basics of creating property graphs

There are essentially four parts or stages to (visual) graph analysis... the actual data, the relationships and graph modeling of that data, notebooks written (in PGQL, eg) for analysis, and visualization of the notebook output in various layouts and highlights. 

The creation of a property graph model from existing tables looks like this...

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

Forced graph layout and community detection


The following force graph layout shows community detection (specifically strongly connected components and the Kosaraj algorithm for community detection in the case)... 

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

The following is an XR Hololens representation of the same where vertex and edge labels are shown as well as the directional relationship of those edges and objects all of which can be manipulated via GGV (gaze, gesture, and voice).

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

Concentric graph layout with rotation and movement


There are numerous types of layouts, each with its own customization settings, tailored for viewing different aspects from different vantage points. Here we see a Concentric layout.

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

The following is an XR Hololens representation of the same. As with all of the XR representations discussed, it is possible to manipulate and analyze the graph visualizations through GGV, however, in this case, I have also added rotation and movement to the final visual representation in order to provide multiple angles and position the graph in a way as best suited to analysis as possible. I've also added spatial audio in this case just for fun though I will be exploring it as an additional tool for analysis and detection as well

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

Visual Data and Graph Modeling


Finally, the video shows a concept for visual data and graph modeling where data sources (in this case basic tables but not limited to such) are represented as objects (cubes) that can be dropped on a common platform/dock. This action results in processing on the Oracle database side to create a graph model, correlations, commonalities, etc., and produce as output other objects that can, in turn, be studied and used in further combinations and analysis.

Oracle Database Exam Prep, Oracle Database Career, Oracle Database Preparation, Oracle Database Jobs, Oracle Database Skill, Extended Reality (XR), XR Hololens Representation

Additional Thoughts


The use cases for properties graphs are literally endless and I have only scratched the service of how they can be visualized in XR. I look forward to putting out more blogs on this topic and other areas of XR with Oracle Cloud, Database soon.

Source: oracle.com

Friday, March 11, 2022

At Last, MongoDB Developers Get Full Autonomous Capabilities

MongoDB Developers, Oracle Database Exam Prep, Oracle Database Certification, Database Preparation, Database Career, Database Skills, Database Job

For many enterprises, JavaScript Object Notation (JSON) documents are critical elements in their online applications. These documents fuel customer experience (CX), sales, and operational applications on the edge, where performance and reliability are critical. JSON enables users to build data structures defined directly by program code. Whenever new developments require data structure changes, developers can implement those changes immediately, without needing to apply to a DBA or wait for a schema upgrade process to complete.

MongoDB has become a leader in the area of JSON databases, and many organizations that use Oracle for enterprise relational applications have turned to MongoDB for their JSON database needs.

A year ago, Oracle announced Autonomous JSON Database (AJD), a new cloud service based upon the foundation of Oracle’s flagship Autonomous Database, as a simple, affordable package designed for JSON-centric developers. It included native JSON features along with a MongoDB-inspired NoSQL API called SODA (Simple Oracle Document Access) and full SQL support for accessing JSON content on Oracle Database. This capability is now enhanced so that the native JSON support is tied directly to the MongoDB API running on Oracle Autonomous Database (ADB), providing a plug-compatible alternative to MongoDB Atlas.

Prior to the introduction of the Oracle Database API for MongoDB, users and developers of MongoDB who wanted to perform analytical queries on document collections had to use an operationally separate database. Operations that ensure overall integrity of data, such as backups, could not be done on all the data together. They had to be done on each database separately, with no guarantee that databases containing logically related data could be recovered in a way that ensures full integrity. Users of separate, differently structured databases that must be coordinated were generally faced with performing that coordination using extract-transform-load (ETL) processes that expose the whole system to problems of data consistency and other faults resulting from operations problems and human error. In addition, the ETL process takes time, meaning that data to be analyzed would often be stale.

Maintaining JSON data in the multi-model AJD, the same database that manages the related table data, overcomes this problem, enabling users to perform SQL queries over JSON documents. Also, AJD offers the benefits of ADB. This means that those same machine learning-driven self-tuning and self-healing capabilities that underpin ADB are also available to MongoDB users who move their data to AJD.

Since Oracle Database users can fold their JSON documents under the Oracle Database umbrella, they can greatly simplify their database operations in the cloud. Using Oracle Database to manage the full range of operational data means that resources, including processors and storage, are allocated at the same rate, and there is just one bill to pay. Some JSON database users may argue that Oracle’s JSON support is less efficient than a specialized DBMS. That may have been true at one time, when JSON documents were stored as objects in tables. However, for the past year, Oracle Database has featured document handling and storage capabilities designed specifically for JSON documents including a new binary data type. In that mode, it is a native JSON database.

AJD is essentially a self-managing, self-healing, dynamically scaling JSON database with MongoDB API compatibility, running on OCI. It is affordably priced for those only using the JSON features, but can be expanded with just one click to the full transaction processing (ATP) configuration of ADB. Customers can also add Oracle Autonomous Data Warehouse (ADW) to the mix. For those who wish to try before they buy, there is an always-free tier.

It is clear that the concentration of all data on one database instance cannot completely solve an enterprise’s data management problems, and that having just one schema for all data is not practical. At the same time, there is a clear benefit with the ability to reduce the total number of database operational assets both from a management and billing perspective, and to blending database operations across models where it makes sense to do so. Using the same core technology for the range of database models required, as in Oracle’s converged database engine, means smoother integration and easier staff training and execution.

Why then use different database models? Some models are more effective in certain use cases than others. JSON documents have established a clear role in supporting applications that require both control over the data format and a high degree of flexibility; the absence of a schema enables developers to evolve applications quickly to address shifting requirements. So, a native JSON document database offers clear advantages for these requirements.

AJD enables users to run their JSON document databases on the self-driving ADB platform, entirely managed by Oracle on OCI, and to coordinate those operations with their other operational databases that are relational in nature, especially those running on Oracle Database. As for the future, Oracle has said that over 90% of its JSON customers are using another data model, suggesting that a greater convergence lies ahead for Oracle users. Those Oracle users who also use other JSON database systems, such as MongoDB or MongoDB-compatible databases, may want to give AJD and the Oracle Database API for MongoDB a good, hard look.

Source: oracle.com

Friday, July 30, 2021

Oracle Database CICD with SQLcl and Liquibase

Part 1: Beginning Continuous Integration for the Database

What is CI/CD

Continuous Integration (CI) and Continuous Delivery/Deployment (CD) are a set of principles or methodologies that empower development teams to deliver code faster, more reliably, and with fewer bugs compared to traditional software development such as the waterfall model. Teams that use CI/CD also usually adhere to some version of the Agile Methodology, working on smaller features as part of a larger overarching requirement in sprints rather than monolithic tasks spanning months or years.

We also have the emergence of DevOps (Developer Operations) as the Agile Methodology collided with the ability to quickly create infrastructure as code in the cloud. As these teams surveyed their new development landscape, it became apparent that they could no longer work in a vacuum, living in their own worlds as they had done in the past. As traditional job roles blurred and more work was done by fewer people, order needed to rise from the chaos of this new complexity.

So, what is CI/CD? What does it do to help with this mess of developers, operations, and stakeholders who need to get features and functions into their software? To answer this, let’s start with the CI of CI/CD, Continuous Integration.

Continuous Integration brings us the ability to have multiple development and operations teams working on different features on a single project simultaneously without stepping all over each other. While this premise sounds too good to be true, there is some truth to be had here.

To have a common thread we can always refer to, this set of posts will be using a common example with real code behind it to illustrate the concepts and processes we will be talking about. So, let’s jump right into it with an example we can reference as we build upon our development process.

Here is our scenario: we have a team of developers working on an application that tracks local trees in a community via a web interface on the city’s web site. A citizen can access this app and enter the information for a historic tree they find in the city. Now this team also uses the Agile Methodology and it’s time for the next sprint. We have a few features we need to get in, mainly the ability to see these trees on a map and the ability to upload a picture with the tree entry form. The tasks are assigned to the developers and the sprint starts.

When does Continuous Integration start? When the tasks are handed out, each developer will copy the code from the latest release in a repository and create their own copy or branch. This latest code release is an exact copy of the code that is currently deployed and running in production. Each developer will also be given a personal development database, more on this later. As the developers finish the tasks they were assigned, they commit their code branch to the repository. Before they create a pull request/merge, they check the current main branch of code in the repository for any changes from other developers merging clean code branches. If found, they will pull these changes down and commit their code again. One of these changes might have affected their code in a negative way and the build process that occurs when a pull request/merge happens will catch this. A code review is scheduled and if accepted, the developer can now create the pull request/merge into the main branch. There is also a build process that occurs every time code is merged into main to catch any bugs or issues that may show up or issues that other developers code may have caused. If so, the issues are addressed, a pull request/merge is created, and the automated testing again happens. Once the testing comes back clean, the code can be merged into the main branch.

Oracle Database CICD, SQLcl and Liquibase, Oracle Database Tutorial and Material, Oracle Database Preparation, Oracle Database Guides, Oracle Database Career, Database Exam Study

Summary Points:


➥ Start Sprint
➥ Pull Code from Main
➥ Create Local Branch
➥ Work on Tickets/Features
➥ Check for Updates in Main
➥ Commit Branch
➥ Create Merge Request
➥ Code Review
➥ Merge into Main/Current Release

What advantages do we gain from this process? First, as we can see throughout this process, we can catch issues before they get into production. By running automated tests on code changes, we can simulate what is going to happen at deployment time and eliminate surprises. This leads to better releases, more confidence in the development team by stakeholders and end users, as well as a higher standard of code from our developers.

Accountability is another advantage. We can see through code commits, merges and reviews exactly what is being put into our code repository and by whom. We can catch any code supply chain issues or hacks because each file and line of code can be reviewed upon a merge. Modern code repositories also track these changes with who and when, so a historical record is always present.

Stateless vs. Stateful


Continuous Integration works very well with stateless files and deployments; static files such as java classes or JavaScript combined with a stateless container deployment; in with the new and out with the old. It very easy to create a new deployment in a docker container with the latest code and replace the old container if working with stateless files.

We see this with blue-green deployment models. In this model, you have your running application container, the blue. The green is your idle newly deployed application container. As some point you switch to the green and all traffic is now using the new version while the blue one is idle. If you need to roll or switch back, you just change back to the idle blue container.

Oracle Database CICD, SQLcl and Liquibase, Oracle Database Tutorial and Material, Oracle Database Preparation, Oracle Database Guides, Oracle Database Career, Database Exam Study

We quickly see these models are not going to work for database deployments. The database has state, transactions are being committed all the time so unless we can afford downtime to copy the entire database, deploy the changes and then resume operations, this poses a challenge. And because of this challenge, DBA’s and database developers are all too often blamed for these deployment bottlenecks. They are often told that databases can never do DevOps let alone CI/CD, it’s too legacy. Where does this leave the DBA and Database Developer? They will be branded with a legacy stigma and seen as a roadblock to CI/CD.

Tools of the Trade


While we wish there was a magic wand to make all database deployments easy and drop right into stateless CD/CD flows, we do have to accept that there is some truth with these DevOps concerns. But not all hope is lost! Oracle Database CI/CD can be a reality, but it requires some shifts in traditional methodologies and processes as well as some new tricks using features and functions of the Oracle Database that may have not been used before.

Let’s refer to our process flow and see where we can add database development specific steps:

Oracle Database CICD, SQLcl and Liquibase, Oracle Database Tutorial and Material, Oracle Database Preparation, Oracle Database Guides, Oracle Database Career, Database Exam Study

The sprint starts and we have our database developers pull the latest code from the latest release. Where is this code? What tools can we use to allow developers to have local copies of our database code? We use a Code Repository.

What is a Code Repository?

There are many code repositories available to us such as Git, GitHub, GitLab and BitBucket. These repositories will help us store our files and provide versioning, accountability and visibility into our development process. But we are starting from scratch here, we have no repository or code release to work with. We will need to create a baseline with a Change Management/Tracking tool.

How can I do Change Management/Tracking with Oracle?

SQLcl with Liquibase.

What’s SQLcl?

Oracle SQLcl (SQL Developer Command Line) is a small, lightweight, Java-based command-line interface for Oracle Database. SQLcl provides inline editing, statement completion, command recall, and also supports existing SQL*Plus scripts. You can download SQLcl from oracle.com and it is installed in the OCI Cloud Shell by default.

What’s Liquibase?

Liquibase is an open-source database-independent library for tracking, managing and applying database schema changes.

How do they work together?

The Liquibase feature in SQLcl enables you to execute commands to generate a changelog for a single object or for a full schema (changeset and changelogs). We also add Oracle specific features and enhancements to Liquibase in SQLcl.

What Database?

For this article, the simplest way to get up and running with an Oracle Database is a free OCI account and an always free Autonomous Database. They come up in minutes and are never going to cost you a dime to use. If you do not have an always free OCI account, you can start here. Once you are logged into your account, you can create an always free Autonomous Database by following this guide here. For our purposes, an Autonomous Transaction Processing database is fine. Just remember the password you used when creating the database; we will need it later.

No Really, What Database?

While we will use a single autonomous database for this article’s examples, in the real world you have a few choices but the most important take away is that all developers MUST have personal databases to work in; and this point cannot be stressed enough. This can be tricky due to many factors but here are some suggestions on making this step a reality in your development organization.

1) Use Multi-tenant in the Oracle Database

Did you know that with 19c and later, you can have up to 3 pluggable databases for free? No need for the multi-tenant license, just create and use. PDBs (pluggable databases) also have the ability to clone just the metadata from an origin PDB. This makes it super simple to create copies of a production code database for all developers. It also aids in the testing automation process we will discuss in the next article. Another quick note is that by installing Oracle REST Data Services (ORDS) on a database enables APIs for cloning and creating PDBs via REST calls.

2) The Autonomous Database in OCI

Using ADB in OCI works very similar to multi-tenant where you can create full and metadata only clones of any ADB. And these ADB instances may only need to be up for minutes to weeks.

3) Reusable Instances

There are many features in the Oracle Database that will allow you to recover state so that developers have clean slates to work with in non multi-tenant instances. Features such as Guaranteed Restore Points/Flashback Database, RMAN duplicates/clones and Data Pump allow you to have clean instances for each developer as sprints start.

4) Docker/Virtual Machines

Either cloud based or local, virtualization technologies can also give developers personal instances to work in with copies of our main code repository within. Developers can also create VM instances of databases in OCI based on the lastet backup of our production instance if need be as well to help with the personal database effort.

Hello Repo


Again referring to our process flow and example, we need to create a baseline or main release so that our developers all start with the same code. To do this, we need to use SQLcl and Liquibase.

Setups Needed

For the examples we will be going over, we will be using git at the command line with our SSH keys pre-set, our repository in GitHub and the project name being db-cicd-project.

You have two choices here:

Manually create the repository or fork the repository that has been pre-created for this article. I would suggest forking it from here:

https://github.com/Mmm-Biscuits/db-cicd-project

Next, set up SSH connection via the following document:

Connecting to GitHub with SSH

A GitHub desktop GUIs is also available.

Now we need to clone it to our local machine/computer/laptop. Navigate to a directory where you would like to store your git repositories locally and issue the clone command:

> git clone git@github.com:YOUR_GITHUB_USERNAME/db-cicd-project.git

The above command will create a directory called db-cicd-project for you and pull any code that was in the repository. It is now time to fill this repository with database goodness.
The First Genschema
The following repository directory structure is what the sample repository that you forked contains:

db-cicd-project
  • apps
  • database
  • etc
    • presetup
    • setup
    • postsetup
  • static
    • css
    • html
    • images
    • js
  • ut
    • utPLSQL
  • README.md
  • version.txt
Note: This directory structure assumes a few things (and we all know what assuming does). The assumption is that the apps directory may contain Application Express apps, so sub directories would be f101 for example. If not using APEX, you could consolidate the static directory and apps directory into a single directory.

Using this directory structure, we are going to start to work with the database and SQLcl now. Using our free ADB, we need to download the wallet that contains all the information for SQLcl to connect to the database. You can look here for the steps to download the wallet.

Once the ADB wallet is downloaded, at a command line, change the directory to the database directory in our repository project. We should be at db-cicd-project -> database. Start SQLcl but do not log into a database yet:

> sql /nolog
 
Next, we have to tell SQLcl where to look for the ADB wallet. First, remember where you downloaded it and we can use the following command to set its location:

SQL> set cloudconfig /DIRECTORY_WHERE_WALLET_IS/WALLET.zip

The naming of the wallet is in the format of Wallet_DB_NAME.zip. So, if I named my database ADB, the wallet name would be Wallet_ADB.zip. And if I put the wallet in my downloads folder and the full command would be:

SQL> set cloudconfig /Users/bspendol/Downloads/Wallet_ADB.zip

Next, we need to connect to the database. The syntax is:

SQL> conn USERNAME@DB_NAME_high/medium/low/tp/tpurgent

The high/medium/low/tp/tpurgent provide different levels of performance for various clients or applications to connect into the database. From the documentation:

➥ tpurgent: The highest priority application connection service for time critical transaction processing operations. This connection service supports manual parallelism.

➥ tp: A typical application connection service for transaction processing operations. This connection service does not run with parallelism.

➥ high: A high priority application connection service for reporting and batch operations. All operations run in parallel and are subject to queuing.

➥ medium: A typical application connection service for reporting and batch operations. All operations run in parallel and are subject to queuing. Using this service the degree of parallelism is limited to four (4).

➥ low: A lowest priority application connection service for reporting or batch processing operations. This connection service does not run with parallelism.

For what we want to do, the high-performance service name will be fine. We also want to connect as the admin user so we can setup a schema and permissions on that schema. With our database being named ADB, we would have the following connect command:

SQL> conn admin@ADB_high
 
And then provide the password you used when creating the ADB at the password prompt:

Password? (**********?)

And we are in. Time to create a schema, give that schema some permissions and then setup a sample for using Liquibase with. Run the following commands:

SQL> create user demo identified by "PAssw0rd11##11" quota unlimited on data;

SQL> grant connect, resource to demo;
 
Now connect as this user:

SQL> conn demo@ADB_high
 
And then provide the password at the password prompt:

Password? (**********?)

Its time to create some sample datababase object for our repository. Run the following scripts included in the sample repository to create some objects:

SQL > @../demo_scripts/create_table.sql

SQL > @../demo_scripts/insert_data.sql

SQL > @../demo_scripts/create_logic.sql

This has created us a table, some data in the table, a trigger with some logic and two procedures. Let’s say this is the base of our application we are going to create. Its now time to use Liquibase to create our baseline and commit it to the repository.

At the SQL prompt, issue the following command:

SQL> lb genschema -split
 
Once this is finished, we can exit out of SQLcl and start to commit our changes to the repository.

SQL> exit

If you take a quick look around the database directory, you will now see folders for indexes, tables, procedures and triggers; all the objects we just created. We also have a controller.xml file. This file is a change log that includes all files in each directory and in the proper order to allow the schema to be deployed correctly to other databases, our CI process.

Time to commit our code to the repository. Change your directory to the top level of the project (the db-cicd-project directory) and run the following command:

> git add .

This command adds our new files to the local staging area. Now we commit the files

> git commit -m "v1.0"

A git commit in takes a snapshot of your local repository or you can think of it as saving the current state. Finally, lets push these files up to the GitHub file repository

> git push

The push command uploads our commit or state to the main repository. Once the push is done, you can see our files in our repository on GitHub. Congratulations, you have just created your code baseline or version 1.0!

Ready, Set, Branch


We have our main code line for our application in the repository. We can now have our developers clone the repository and start their assigned tickets/task in this development cycle or sprint. The issue with this is that they would all be committing to main and probably stepping all over each other. This requires each developer to create a branch of the repository that they can work in and commit their code to.

Let’s pretend we are developer who has been given the URL to clone the repository and start coding. They start by using git to clone to their local machine:

> git clone git@github.com:YOUR_GITHUB_USERNAME/db-cicd-project.git
 
Now they need to create a personal branch of this code:

> git checkout -b BRANCH_NAME

A good practice is to have the developers name the branch to relate to a ticket or sprint they are working on with their names in the branch. Here are some examples:

> git checkout -b TICKET#_USERNAME

> git checkout -b JIRA_TICKET#_USERNAME

> git checkout -b SPRINT#_USERNAME

For our example here, let’s use the following (use your name, not mine). Run this command in the top level folder of the project (db-cicd-project)

> git checkout -b sprint1_brian.spendolini

And you will see the response:

> Switched to a new branch 'sprint1_brian.spendolini'

We can now start developing and committing code to the repository without mixing our changes with the main code line. You can always issue a git status to see what branch you are in:

> git status
On branch sprint1_brian.spendolini
nothing to commit, working tree clean

Only the Changes


Back to our sprint. If you remember from our example scenario, the first ticket says that we need to add a new column to the trees table so that citizens can upload a picture of the tree they are entering. OK, simple enough task.

Once we are in our local git repository for the project db-cicd-project, we move the the database directory. And as before, we use SQLcl to log into our autonomous database:

> sql /nolog

Set the wallet location again (your directory path will be different):

SQL> set cloudconfig /Users/bspendol/Downloads/Wallet_ADB.zip
 
And connect to the database:

SQL> conn demo@ADB_high
 
And then provide the password at the password prompt (password is PAssw0rd11##11):

Password? (**********?)

Time to add the column. We can issue the following SQL to add the personal_interest column to the employee table:

SQL> alter table trees add (tree_picture blob);
Table EMPLOYEES altered.
 
Ticket done, time to generate the schema again using Liquibase.

SQL> lb genschema -split
 
We can exit SQLcl and go back to the top level of our local git repository. In the db-cicd-project, we issue a git add

> git add .

And then a commit

> git commit -m "ticket1"

Then we push the new code up to our repository. This push will be slightly different because we are pushing to a branch now. If you issue a git push, you will see something similar to below:

> git push
fatal: The current branch sprint1_brian.spendolini has no upstream branch.
To push the current branch and set the remote as upstream, use

    git push --set-upstream origin sprint1_brian.spendolini

So we need to issues the push with our branch this one time:

> git push --set-upstream origin sprint1_brian.spendolini
 
If you go into the GitHub web UI, you can see in this repository that a new branch has been created and that only the table file has been updated as expected.

Oracle Database CICD, SQLcl and Liquibase, Oracle Database Tutorial and Material, Oracle Database Preparation, Oracle Database Guides, Oracle Database Career, Database Exam Study

The other files which contain the procedure and trigger code have not been changed. Again, Liquibase is tracking the changes for us, and we can see it in action here.

Apply Yourself


Seeing is believing so let’s do exactly that; let’s apply our master code line into a schema in our database then apply the new branch and see what Liquibase does.

We need to switch back to our master branch in our local code repository on our local machines. Before we do that, we can see what happened when we do this switch. Go into the database directory while still on this branch we just committed to. Take a look at the trees_table.xml file. We should see the new column in the XML as:

         <COL_LIST_ITEM>
            <NAME>TREE_PICTURE</NAME>
            <DATATYPE>BLOB</DATATYPE>
         </COL_LIST_ITEM>
      </COL_LIST>
 
Now issue the following git command:

> git checkout master
 
And look at the employees_table.xml again. You can see that the last column in this file is SUBMITION_DATE and no longer TREE_PICTURE.

         <COL_LIST_ITEM>
            <NAME>SUBMITION_DATE</NAME>
            <DATATYPE>TIMESTAMP</DATATYPE>
            <SCALE>6</SCALE>
         </COL_LIST_ITEM>
      </COL_LIST>
 
Why is that? It’s because you switched branches to the master branch where we have our baseline code. We have yet to merge this code into that main branch so the new column change only exists in our development branch. Let’s use this to our advantage. While on the master branch, start up SQLcl and login as the admin user:

> sql /nolog

SQL> set cloudconfig /Users/bspendol/Downloads/Wallet_ADB.zip

SQL> conn admin@ADB_high

And we will create a new schema

SQL> create user test identified by "PAssw0rd11##11" quota unlimited on data;

SQL> grant connect, resource to test;

SQL> conn test@ADB_high
Password? (**********?) **************
Connected.

We need to be in the database directory of our local project. We can use some of SQLcl built in functionality to get there if not already there. We can navigate directories with the cd command. If you are in the tables directory under the database directory, you can simply issue a:

SQL> host cd ..

And move up a directory into the database directory in our project home. We can also use the host command with SQLcl to see where we are:

SQL> host pwd
/Users/bspendol/git/db-cicd-project/database

Ensure you are in the /db-cicd-project/database directory where mine would be as above:
/Users/bspendol/git/db-cicd-project/database

You can also issue a host ls command to see the files in that directory:

SQL> host ls
controller.xml        index            table
database_files_here    procedure        trigger
 
we are looking to use the controller.xml file.

Quick checkpoint: We are logged into our database as the test user we just made, we are on the master code branch in the local repository and we are in the database directory in our project home. Once here, we are going to use Liquibase to create the objects from our master branch. Issue the following command:

SQL> lb update -changelog controller.xml

Once you issue this command, you will see all our objects being created in the database.

SQL> lb update -changelog controller.xml
ScriptRunner Executing: table/trees_table.xml::96726c6d630653c9a9169df8b67089f2cdee1135::(DEMO)-Generated -- DONE
ScriptRunner Executing:
procedure/admin_email_set_procedure.xml::9d1175a5b6ca6d0c969a2eb183062e0a873ee226::(DEMO)-Generated -- DONE
ScriptRunner Executing: index/tree_id_pk_index.xml::b4dd6c2359e7f1e881b55ba728056510d537967a::(DEMO)-Generated -- DONE
ScriptRunner Executing: trigger/set_date_bi_trigger.xml::3b0d8da4c19a11b80f035a748c9b40752f010110::(DEMO)-Generated -- DONE

######## ERROR SUMMARY ##################
Errors encountered:0

######## END ERROR SUMMARY ##################
 
Now, we can move to our development branch and apply that to this schema. Exit out of SQLcl:

SQL> exit
 
Change branches (remember your branch will be named different, unless you are a clone of me with the same name..if so email me please):

> git checkout sprint1_brian.spendolini
Switched to branch 'sprint1_brian.spendolini'
Your branch is up to date with 'origin/sprint1_brian.spendolini'.

And log back into the database as this test user:

> sql /nolog

SQL> set cloudconfig /Users/bspendol/Downloads/Wallet_ADB.zip

SQL> conn test@ADB_high

And now, using our development branch, we will apply the changes to this schema:

SQL> lb update -changelog controller.xml
ScriptRunner Executing: table/trees_table.xml::f81a149311b20a5a1dfe95a35108b8728df33b7f::(DEMO)-Generated -- DONE

######## ERROR SUMMARY ##################
Errors encountered:0

######## END ERROR SUMMARY ##################
 
There are 2 tables that Liquibase uses to track changes, DATABASECHANGELOG and DATABASECHANGELOG_ACTIONS. There is also a view that combines these tables for a more readable format, DATABASECHANGELOG_DETAILS. If we take a look at the DATABASECHANGELOG_DETAILS view, we can see that only an alter table was done and that the table was not dropped and recreated in the SQL column:

SQL
--------------------------------------------
ALTER TABLE "TREES" ADD ("TREE_PICTURE" BLOB)
 

This would be not only the behavior you would see in say a production instance, but more importantly the behavior you would expect a change management tool to be executing.

Merge Ahead


You now have the tools to start change management with SQLcl, Liquibase and a git repository for your development group or organization. As with all new processes, start slow. Maybe start with just getting everyone used to committing code to a central repository using git. But once we start adding these building blocks, we can continue down the CICD road to the next stages.

This process also allows you to start combining your database sprint code with stateless application code in the same repository setting the entire development team up for a CICD process. No longer are database developers and DBAs left out in the cold being called legacy when they can now uptake the same change management and repository practices that other development teams have enjoyed.

Source: oracle.com